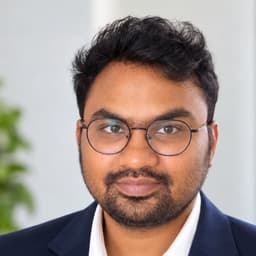
About / By Dinesh Maluchuru
Hi, I’m Dinesh.
I’m a Senior Data & ML Engineer at Microsoft, with more than nine years of experience building data platforms, analytics and ML pipelines across Microsoft, Amazon and JPMorgan Chase. Here I work through the ideas behind that work — one explanation, example and experiment at a time.
What I actually work on
My day job lives close to data: ingestion and storage pipelines, the analytics on top of them, and — more recently — using language models as part of how that data gets evaluated. My work at Microsoft has included OneDrive/SharePoint log and storage-cost analytics, data infrastructure and LLM evaluation for OneNote Copilot, and Windows analytics. Before that, at Amazon, I modelled the package-delivery lifecycle and the pipelines behind last-mile logistics and financial reporting; at JPMorgan Chase I migrated an Oracle data platform onto Spark and partnered with the lending and cards businesses on analytics.
The through-line is less about any one tool and more about a habit: start from the question someone is actually trying to answer, model the domain so the data can answer it, and keep an eye on what it all costs to run as it scales.
Why I write this lab
I use this lab to work through the underlying ideas, not just collect recipes. The writing connects data engineering, Spark, systems design, deep learning and ML practice through sequenced lessons and worked examples. The aim is to make an idea concrete enough to test, with the sources kept in view and the limits stated honestly.
I also mentor junior engineers on data engineering, LLM adoption and career development. The same approach shapes these pages: explain the mechanism, work through an example, then change an assumption and see what breaks.
Background
I studied Electrical Engineering at IIT Madras, where I did a dual degree (B.Tech and M.Tech) between 2012 and 2017; my master’s thesis was on vehicle classification using image processing and machine learning. Outside the day job I’m most interested in LLM platforms and evaluation, AI agents, and the engineering that makes deep-tech systems actually reliable.
How this site works
The lab is organised around questions and learning paths rather than a publishing calendar. Read at your own pace, skip what you already know, and come back when an idea becomes useful. There’s no account to create and no streak to protect — bookmarks and completion marks live only in this browser’s local storage, so they don’t sync across devices and clearing site data removes them. “Complete” means you marked a lesson done, not that you passed an assessment.
The library is curated and it evolves. Lessons can be corrected, consolidated, or retired, and a review label describes an editorial process — not a guarantee that every claim holds in every setting. Check the assumptions, reproduce the examples, and follow the linked sources.
Read the editorial policy →Find a learning path →LinkedIn ↗GitHub ↗